
Configure Qdrant Cloud Clusters
Qdrant Cloud offers several advanced configuration options to optimize clusters for your specific needs. You can access these options from the Cluster Details page in the Qdrant Cloud console.
The cloud platform does not expose all configuration options available in Qdrant. We have selected the relevant options that are explained in this page.
In addition, the cloud platform automatically configures the following settings for your cluster to ensure optimal performance and reliability:
- The maximum number of collections in a cluster is set to 1000. Larger numbers of collections lead to performance degradation. For more information see Multitenancy.
- To improve performance and reliability, strict mode is activated by default for new collections, with the following restrictions:
- Retrieving points by filtering on a non indexed payload key is not allowed (
unindexed_filtering_retrieveis set tofalse). - Updating points by filtering on a non indexed payload key is not allowed (
unindexed_filtering_updateis set tofalse). - The maximum number of payload indexes per collection is set to 100 (
max_payload_index_countis set to100).
- Retrieving points by filtering on a non indexed payload key is not allowed (
- The cluster mode is automatically enabled to allow distributed deployments and horizontal scaling.
- The maximum amount of payload indexes per collection is set to 100. Larger numbers of payload indexes lead to performance degradation (starting with Qdrant v1.16.0).
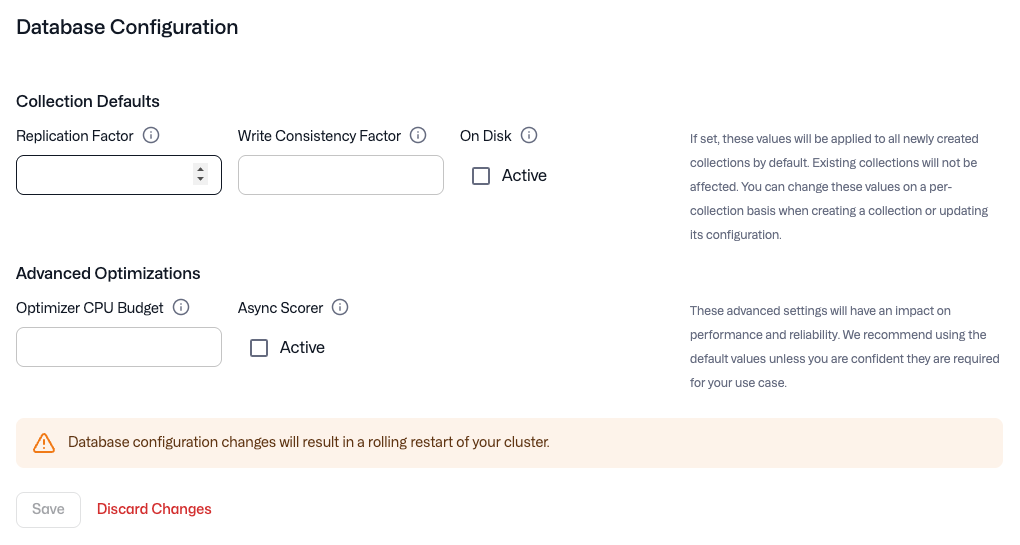
Collection Defaults
You can set default values for the configuration of new collections in your cluster. These defaults will be used when creating a new collection, unless you override them in the collection creation request.
You can configure the default Replication Factor, the default Write Consistency Factor, and if vectors should be stored on disk only, instead of being cached in RAM.
Refer to Qdrant Configuration for more details.
Advanced Optimizations
Configuring these advanced settings will have an impact on performance and reliability. We recommend using the default values unless you are confident they are required for your use case.
Optimizer CPU Budget
Configures how many CPUs (threads) to allocate for optimization and indexing jobs:
- If 0 or empty (default) - Qdrant keeps one or more CPU cores unallocated from optimization jobs, depending on the number of available CPUs, optimization jobs, and traffic load.
- If negative - Qdrant subtracts this number of CPUs from the available CPUs and uses them for optimizations
- If positive - Qdrant uses this exact number of CPUs for optimizations
Async Scorer
Enables async scorer which uses io_uring when rescoring. This setting is deprecated. On clusters running Qdrant v1.20.0 or later, Qdrant Cloud sets the async I/O mode itself and this setting no longer has an effect. Refer to Qdrant under the hood: io_uring and Large Scale Search for more details.
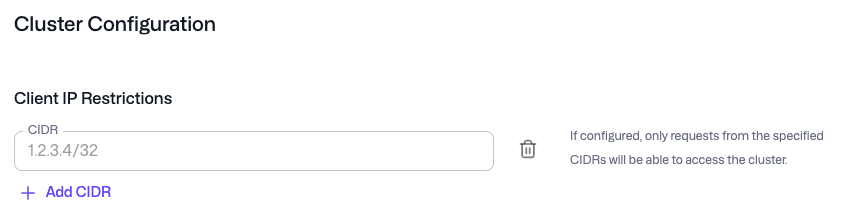
Client IP Restrictions
If configured, only the chosen IP ranges will be allowed to access the cluster. This is useful for securing your cluster and ensuring that only clients coming from trusted networks can connect to it.
Restarts and Downtime
These operations restart the nodes of a cluster:
- Version upgrades.
- Vertical scaling of the CPU or memory, up or down.
- Decreasing the disk size. Each node is replaced by a smaller one and its shards are transferred.
- Changing the collection defaults and the advanced settings of the cluster: replication factor, write consistency factor, async scorer, optimizer CPU budget, vectors on disk, log level, and audit logging.
- Enabling Database API keys with granular access control.
- Enabling or disabling Cloud Inference.
These changes take effect without a restart: increasing only the disk size, client IP restrictions, the restart mode itself, the shard rebalance strategy, the disk speed tier, the cost allocation label, and cluster labels.
Downtime during a restart depends on the configuration of your cluster and its collections:
| Cluster | Restart mode | Downtime |
|---|---|---|
| Multi-node, with at least one collection that has a replication factor of 2 or more | Rolling: nodes restart one at a time | None for replicated collections. The cluster stays available |
| Multi-node, with all collections at a replication factor of 1 | Parallel: all nodes restart at the same time | A short downtime, but a faster restart |
| Single node | Not applicable | A short downtime while the node restarts |
| Free tier | Not applicable | Version upgrades happen with downtime |
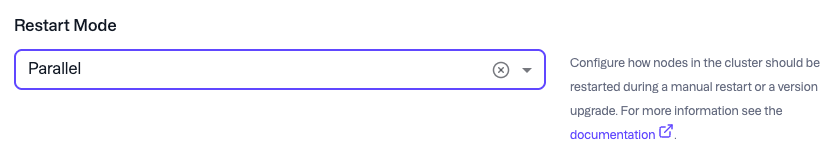
The cloud platform chooses the restart mode automatically. To override the default, use the restart mode setting in the advanced configuration section of the Cluster Details page.
To avoid downtime, run at least 3 nodes, and set a replication factor of at least 2 on the collections that must stay available. See Scale Clusters and Update Clusters for the steps.
Shard Rebalancing
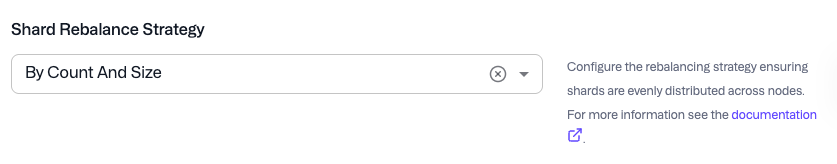
Qdrant Cloud continuously monitors the distribution of shards across your cluster’s nodes and rebalances them in the background to keep data evenly distributed. This also happens whenever you scale your cluster horizontally. The rebalancing target is the total shard count and/or size per node across all of your collections combined, not per collection, so a single collection can look unevenly placed even while the cluster as a whole is balanced by that measure.
Qdrant Cloud offers three strategies for shard rebalancing:
by_count_and_size(default): This strategy will rebalance the shards based on the number of shards and their size. It will ensure that all nodes have the same number of shards and that shard sizes are evenly distributed across nodes.by_count: This strategy will rebalance the shards based on the number of shards only. It will ensure that all nodes have the same number of shards, but shard sizes may not be balanced evenly across nodes.by_size: This strategy will rebalance the shards based on their size only. It will ensure that shards are evenly distributed across nodes by size, but the number of shards may not be even across all nodes.
If you manually move a shard (see Moving Shards) while automatic rebalancing is active, and that move leaves a node’s shard count or size outside the target, automatic rebalancing can move a shard back to correct it. To manually control shard distribution across nodes, deactivate automatic shard rebalancing by selecting Disabled for the Shard Rebalance Strategy option.
Rename a Cluster
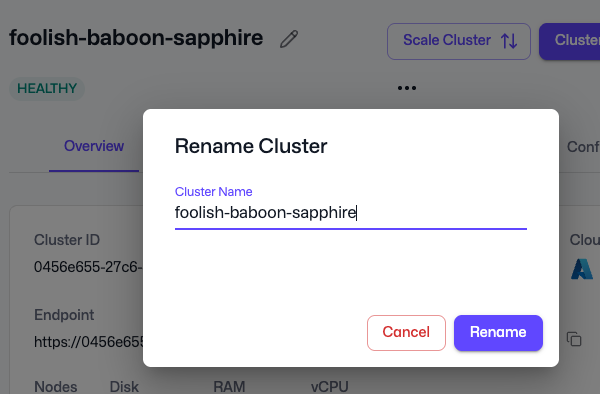
You can rename a Qdrant Cluster from the cluster’s detail page.
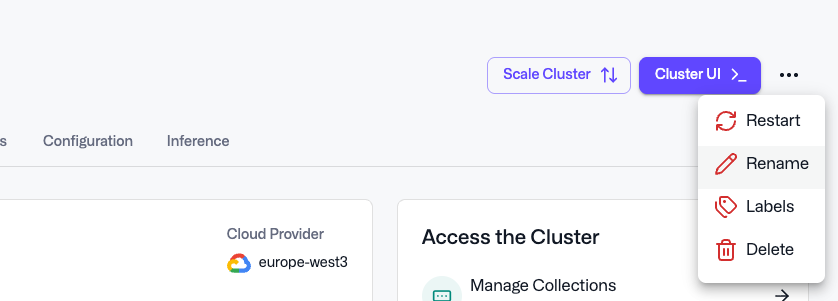
Renaming a cluster does not affect its functionality or configuration. The cluster’s unique ID and cluster URLs will remain the same.
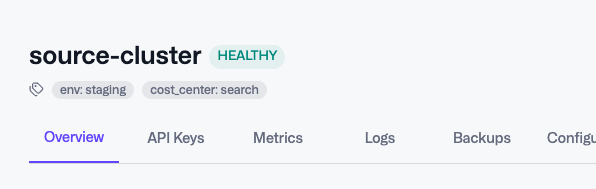
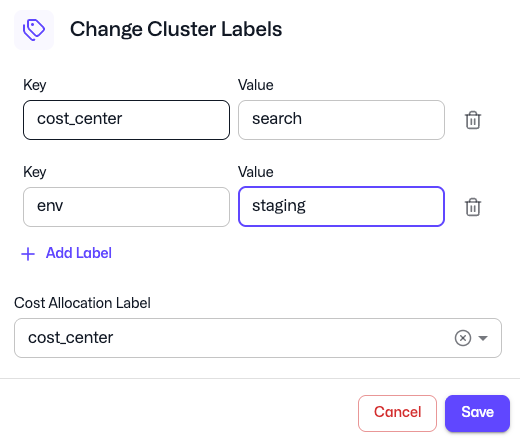
Adding Labels to a Cluster
You can add labels to a Qdrant Cluster from the cluster’s detail page. Labels are key-value pairs that help you organize and manage your clusters. You can also configure which label will be used for cost attribution and shown in consumption reports.
Audit Logging
You can activate audit logs for your cluster in the cluster configuration tab of the cluster details page. Audit logs provide a record of all API calls made to the cluster. This is useful for security and compliance purposes.
Audit logs are available for all paid clusters, starting with Qdrant v1.17.0; the endpoint for downloading logs is available from Qdrant v1.17.1.
The following information is tracked:
- The performed action (e.g.
list_collections,create_collection,upsert_points, etc.) - The timestamp of the action
- The API key ID used to perform the action, or the User ID if the action was performed through the Web UI
- The result of the action (success or failure)
- The IP address from which the action was performed
You can configure the rotation (daily/hourly) and retention of your log files (how many of the log files should be kept).
Audit log files will be stored on your cluster’s encrypted storage disk. You need to ensure that you have enough storage capacity available. Storage capacity and usage can be viewed in your cluster metrics.
Audit Log Output on Hybrid Cloud
On Hybrid Cloud clusters running Qdrant v1.20.0 or later, you can choose where audit log entries are written under “Write Audit Logs To”: File, Stdout, or both. File is selected by default. Managed Cloud clusters always write to file.
File stores the entries on the cluster storage disk. It is required for log download and the /audit/logs API. Rotation and Max Log Files apply to file output only.
Stdout writes one JSON line per event to the standard output of the Qdrant container, so your log collector can pick it up together with the regular container logs. Every audit line carries "kind": "audit" to tell it apart from other log entries. With Stdout only, nothing is written to disk, and the /audit/logs API returns no entries. See Audit Log Output for the details.
You can also set the output through the Qdrant Cloud API (output in the audit logging configuration), the output attribute of the Terraform provider, and the --audit-log-output flag of the Qdrant Cloud CLI.
You can download the audit logs from your cluster through the Qdrant API:
curl -X POST 'https://node-N-YOUR-CLUSTER-URL:6333/audit/logs' \
  -H 'api-key: QDRANT_API_KEY' \
  -H 'Content-Type: application/json' \
  -d '{
    "limit": 50,
    "time_from": "2026-03-26T00:00:00Z",
    "time_to": "2026-03-27T00:00:00Z",
    "filters": {
      "result": "denied",
      "collection": "my_collection"
    }
  }'
Or without a filter:
curl -X POST 'https://node-N-YOUR-CLUSTER-URL:6333/audit/logs' \
  -H 'api-key: QDRANT_API_KEY' \
  -H 'Content-Type: application/json' \
  -d '{}'
 Ready to try Qdrant?