> Explore Qdrant's agent skills catalog at https://skills.qdrant.tech/
> Search the documentation at https://skills.qdrant.tech/search?query=your+query+here
> Use this file to discover all available pages: https://qdrant.tech/llms.txt
# Sparse Vector Search
[Sparse vectors](https://qdrant.tech/articles/sparse-vectors/index.md) are a flexible way to represent data for search purposes, from classic BM25-based search, to semantic search, and [collaborative filtering](https://qdrant.tech/documentation/tutorials-search-engineering/collaborative-filtering/index.md). Each term in the vocabulary corresponds to one or more dimension of the sparse vector, and the values in those dimensions represent the weight of that term in the document. Weights can come from transformer-based models that capture semantic meaning, like [SPLADE++](#splade) and [miniCOIL](#minicoil), or from document statistics for use with the [BM25](#bm25) ranking algorithm.
## SPLADE++
The SPLADE (Sparse Lexical and Dense) family of models are transformer-based models that generate sparse vectors out of text. These models combine the benefits of traditional lexical search with the power of transformer-based models by accounting for homonyms and synonyms. SPLADE models achieve this by expanding the vocabulary of the input text using contextual embeddings from the transformer model. For example, when processing the input text "time travel", a SPLADE model may expand the input to include related terms like "temporal", "journey", and "chronology". This expansion allows SPLADE models to capture the semantic meaning of the text while still leveraging the strengths of lexical search.
The advantage of using SPLADE models is that they [perform better](https://qdrant.tech/articles/sparse-vectors/index.md#splade) than traditional BM25. They also have several downsides though. First, because they use a fixed vocabulary, you can't use SPLADE models to find terms that are not in the vocabulary, such as product IDs and out-of-domain language (words not seen in training). Secondly, because they are transformer-based models, SPLADE models are slower and require more computational resources than the traditional BM25 model.
On [Qdrant Cloud](https://qdrant.tech/documentation/inference/cloud-inference/index.md), you can use the SPLADE++ model with inference. Alternatively, you can generate vectors on the client side using the [FastEmbed](https://qdrant.tech/documentation/fastembed/index.md) library.
```http
POST /collections/books/points/query
{
"query": {
"text": "time travel",
"model": "prithivida/splade_pp_en_v1"
},
"using": "title-splade",
"limit": 10,
"with_payload": true
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/query-splade/index.md).
For a tutorial on using SPLADE++ with FastEmbed, refer to [How to Generate Sparse Vectors with SPLADE](https://qdrant.tech/documentation/fastembed/fastembed-splade/index.md).
## miniCOIL
[miniCOIL](https://qdrant.tech/articles/minicoil/index.md) strikes a balance between the flexibility of BM25 and the performance of SPLADE++. miniCOIL is a transformer-based model that generates sparse vectors for text. Unlike SPLADE++, it doesn't use a vocabulary expansion mechanism. To capture the context and meaning of terms, the model generates a four-dimensional vector for each term. miniCOIL does not use a fixed vocabulary, making it an effective model for lexical search that ranks results based on the contextual meaning of keywords.
miniCOIL can be [used with the FastEmbed library](https://qdrant.tech/documentation/fastembed/fastembed-minicoil/index.md).
## BM25
You can also run [BM25](https://qdrant.tech/documentation/search/text-search/full-text-search/index.md#bm25) on sparse vectors. Qdrant provides native support for BM25 through an [inference model](https://qdrant.tech/documentation/inference/inference-bm25/index.md) that generates sparse vectors, or you can generate vectors on the client side using the [FastEmbed](https://qdrant.tech/documentation/fastembed/index.md) library.
The sparse vector BM25 model supports the same [text processing](https://qdrant.tech/documentation/search/text-search/text-filtering/index.md#text-processing) options as text indices, including tokenization, lowercasing, ASCII folding, stemming, and stopword removal. A notable difference with text indices is that the sparse vector BM25 model defaults to English stemming and stopword removal. If you are using a language other than English, ensure that you [configure](#bm25-text-processing) the model accordingly.
To use the sparse vector BM25 model, configure a sparse vector:
```http
PUT /collections/books
{
"sparse_vectors": {
"title-bm25": {
"modifier": "idf"
}
}
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/create-bm25-collection/index.md).
Note the [IDF modifier](https://qdrant.tech/documentation/manage-data/indexing/index.md#idf-modifier), which configures the sparse vector for queries that use the inverse document frequency (IDF). By default, IDF statistics are computed over all data in the shard being queried; see [Per-Tenant Scoring Statistics](https://qdrant.tech/documentation/manage-data/multitenancy/index.md#per-tenant-scoring-statistics) to scope them to a subset, such as a single tenant.
Now you can ingest data. The following example ingests a book with its title represented as a sparse vector generated by the sparse vector BM25 model:
```http
PUT /collections/books/points?wait=true
{
"points": [
{
"id": 1,
"vector": {
"title-bm25": {
"text": "The Time Machine",
"model": "qdrant/bm25"
}
},
"payload": {
"title": "The Time Machine",
"author": "H.G. Wells",
"isbn": "9780553213515"
}
}
]
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/ingest-bm25-point/index.md).
After ingesting data, you can query the sparse vector. The following example searches for books with "time travel" in the title using the sparse vector BM25 model:
```http
POST /collections/books/points/query
{
"query": {
"text": "time travel",
"model": "qdrant/bm25"
},
"using": "title-bm25",
"limit": 10,
"with_payload": true
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/query-bm25/index.md).
### Configuring BM25 Parameters
The sparse vector BM25 model has three adjustable parameters, based on the BM25 [ranking function](https://en.wikipedia.org/wiki/Okapi_BM25#The_ranking_function), that you can set at ingest time to optimize search results for your specific use case:
- `k`. Controls term frequency saturation. Higher values increase the influence of term frequency. Defaults to 1.2.
- `b`. Controls document length normalization. Ranges from 0 (no normalization) to 1 (full normalization). A higher value means longer documents have less impact. Defaults to 0.75.
- `avg_len`. Average number of words in the field being queried. Defaults to 256.
For instance, book titles are generally shorter than 256 words. To achieve more accurate scoring when searching for book titles, you could calculate or estimate the average title length and set the `avg_len` parameter accordingly:
```http
PUT /collections/books/points?wait=true
{
"points": [
{
"id": 1,
"vector": {
"title-bm25": {
"text": "The Time Machine",
"model": "qdrant/bm25",
"options": {
"avg_len": 5.0
}
}
},
"payload": {
"title": "The Time Machine",
"author": "H.G. Wells",
"isbn": "9780553213515"
}
}
]
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/ingest-bm25-avglen/index.md).
When designing a multi-representation collection (combining short fields like titles and tags with longer body text), the practical default is sparse vector BM25 on the shorter, structured fields with dense vectors carrying the longer ones. BM25F is the principled extension for multi-field text of varying length; Qdrant doesn't support it natively today, but the [Multi-Representation Search](https://qdrant.tech/documentation/tutorials-search-engineering/multi-representation-search/index.md) tutorial shows the workaround: separate sparse vectors per field, fused via the Query API.
### BM25 Text Processing
Before the sparse vector BM25 model can generate a vector for a text, Qdrant breaks the text down into individual tokens (words) and applies several normalization steps to them. This ensures that searches can match variations of words. For query tokens to match the indexed tokens, the query text must go through the same steps.
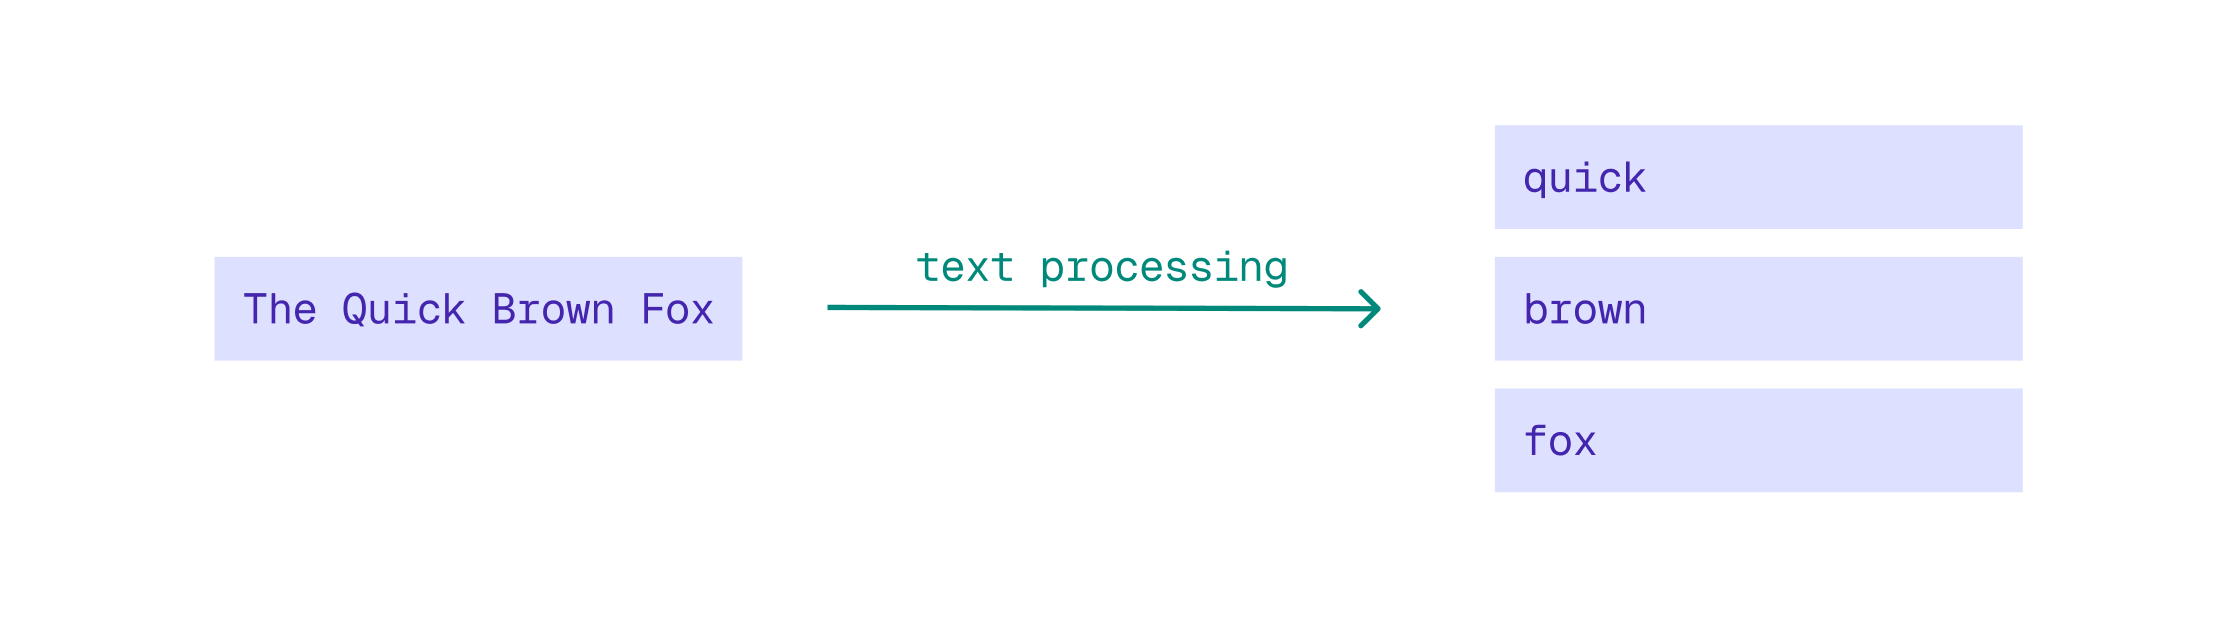
*Text processing turns a sentence into tokens. By default, the sparse vector BM25 model lowercases tokens, removes English stopwords, and applies English stemming.*
By default, the sparse vector BM25 model uses English-specific settings for tokenization, stemming, and stopword removal. Words are reduced to their English root form, and common English stopwords are removed. If your data is not in English, this leads to suboptimal search results. To achieve optimal results for other languages, configure language-specific settings for the sparse vector BM25 model.
#### Stemming and Stopwords
To configure stemming and stopword removal, use the following options:
- `language`: sets the language for stemming and stopword removal. Defaults to `english`.
- `stemmer`: defaults to stemming for `language` (if set), but can be configured independently. Set to `{"type": "none"}` to explicitly disable stemming.
- `stopwords`: defaults to a set of stopwords for `language` (if set) but can be configured independently. You can configure a specific `language` and/or configure an explicit set of stopwords that will be merged with the stopword set of the configured language. Configure an empty stopwords set to disable stopword removal.
For example, to use Spanish stemming and stopwords during data ingestion, use:
```http
PUT /collections/books/points?wait=true
{
"points": [
{
"id": 1,
"vector": {
"title-bm25": {
"text": "La Máquina del Tiempo",
"model": "qdrant/bm25",
"options": {
"language": "spanish"
}
}
},
"payload": {
"title": "La Máquina del Tiempo",
"author": "H.G. Wells",
"isbn": "9788411486880"
}
}
]
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/ingest-bm25-spanish/index.md).
At query time, use the exact same parameters to ensure consistent text processing:
```http
POST /collections/books/points/query
{
"query": {
"text": "tiempo",
"model": "qdrant/bm25",
"options": {
"language": "spanish"
}
},
"using": "title-bm25",
"limit": 10,
"with_payload": true
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/query-bm25-spanish/index.md).
To use only stemming, set an empty stopword list. To use only stopword removal, disable stemming by setting `stemmer: {"type": "none"}`.
#### ASCII Folding
ASCII folding is the process of removing diacritics (accents) from characters. By removing diacritics, ASCII folding enables you to ignore accents when searching. For instance, with ASCII folding enabled, searching for "cafe" matches both "cafe" and "café".
To enable ASCII folding, set the `ascii_folding` option to `true` at both ingest and query time:
```http
POST /collections/books/points/query
{
"query": {
"text": "Mieville",
"model": "qdrant/bm25",
"options": {
"ascii_folding": true
}
},
"using": "author-bm25",
"limit": 10,
"with_payload": true
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/query-bm25-ascii-folding/index.md).
#### Tokenizer
The tokenizer breaks down text into individual tokens (words). By default, the sparse vector BM25 model uses the `word` tokenizer, which splits text based on word boundaries like whitespace and punctuation. This method is effective for Latin-based languages but may not work well for languages with non-Latin alphabets or languages that do not use spaces to separate words. For those languages, use the `multilingual` tokenizer. This tokenizer supports multiple languages, including those with non-Latin alphabets and non-space delimiters.
```http
POST /collections/books/points/query
{
"query": {
"text": "村上春樹",
"model": "qdrant/bm25",
"options": {
"tokenizer": "multilingual"
}
},
"using": "author-bm25",
"limit": 10,
"with_payload": true
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/query-bm25-multilingual-tokenizer/index.md).
#### Language-neutral Text Processing
*Available as of v1.19.0*
In some situations, you may want to disable language-specific processing altogether. For example, when searching for author names, that don't necessarily conform to the rules of a specific language.
To disable language-specific processing, set the following options:
- `stemmer`: set to `{"type": "none"}` to explicitly disable stemming.
- `stopwords`: configure an empty stopwords set to disable stopword removal.
- `tokenizer`: set to `multilingual` for language-aware tokenization that automatically detects the script and applies the appropriate segmentation for each language.
- Optionally, set `ascii_folding` to `true` to enable ASCII folding and ignore diacritics.
```http
POST /collections/books/points/query
{
"query": {
"text": "Mieville",
"model": "qdrant/bm25",
"options": {
"stemmer": {"type": "none"},
"stopwords": {},
"tokenizer": "multilingual",
"ascii_folding": true
}
},
"using": "author-bm25",
"limit": 10,
"with_payload": true
}
```
> This snippet is also available in Python, Typescript, Rust, Java, Csharp, and Go. See the [full snippet](https://qdrant.tech/documentation/snippets/text-search/query-bm25-language-neutral/index.md).