
Build a Semantic Search API with Qdrant
| Time: 30 min | Level: Beginner | Output: GitHub |  |
|---|
This tutorial shows you how to build and deploy your own neural search service to look through descriptions of companies from startups-list.com and pick the most similar ones to your query. The website contains the company names, descriptions, locations, and a picture for each entry.
A neural search service uses artificial neural networks to improve the accuracy and relevance of search results. Besides offering simple keyword results, this system can retrieve results by meaning. It can understand and interpret complex search queries and provide more contextually relevant output, effectively enhancing the user’s search experience.
Workflow
To create a neural search service, you will need to transform your raw data and then create a search function to manipulate it. You will:
- Download a sample dataset
- Load the data into Qdrant Cloud, which turns each description into a vector with an embedding model
- Create a neural search API
- Serve it using FastAPI


Prerequisites
To complete this tutorial, you will need:
- A Qdrant Cloud account for a Free Tier Qdrant Cloud Cluster.
- Raw parsed data from startups-list.com.
- Python version >=3.10
Prepare Sample Dataset
To conduct a neural search on startup descriptions, you must first encode the description data into vectors. To process text, you can use any pre-trained embedding model.
In this tutorial, Qdrant Cloud runs the model for you through Cloud Inference, so you don’t need to download it.
You will be using a pre-trained model called all-MiniLM-L6-v2, one of the free models on Qdrant Cloud.
Note: Before you begin, create a project directory and a virtual python environment in it.
First you need to download the dataset into the project directory. It is a single JSON file of about 22 MB with all 40,474 startups.
curl -O https://storage.googleapis.com/generall-shared-data/startups_demo.json
Create a Qdrant Cloud Cluster
Next, you need to manage all of your data using a vector search engine. Qdrant lets you store, update or delete created vectors. Most importantly, it lets you search for the nearest vectors via a convenient API.
- Register for a Qdrant Cloud account using your email, Google, or GitHub credentials.
- Under Create a Free Cluster, enter a cluster name and select your preferred cloud provider and region. Click Create Free Cluster.
- Copy the API key when prompted and store it somewhere safe, as it won’t be displayed again.
- Copy the Cluster Endpoint. It should look something like
https://xxx.cloud.qdrant.io. - Store both as environment variables in your terminal, so the code can read them.
export QDRANT_URL="https://xxx.cloud.qdrant.io"
export QDRANT_API_KEY="your-api-key"
Note: To run Qdrant on your own machine instead, follow the Local Quickstart and generate the embeddings locally, as the hybrid search tutorial does with FastEmbed.
Upload Data to Qdrant
- Install the official Python client to best interact with Qdrant.
pip install "qdrant-client>=1.19.1"
At this point, you should have startup records in the startups_demo.json file and a Qdrant Cloud cluster.
Now you need to upload all startup data into the search engine. Start Python in the terminal where you set the environment variables, and run the following steps in that session.
- Read the raw data file. Each line holds one startup with its name, description, city, and other fields.
import json

with open("startups_demo.json") as file:
    startups = [json.loads(line) for line in file]
- Create a client object for Qdrant. With
cloud_inference=True, Qdrant Cloud Inference generates the embeddings from the text you send.
import os

from qdrant_client import QdrantClient, models

client = QdrantClient(
    url=os.environ["QDRANT_URL"],
    api_key=os.environ["QDRANT_API_KEY"],
    cloud_inference=True,
)
- Related vectors need to be added to a collection. Create a new collection for your startup vectors.
if not client.collection_exists("startups"):
    client.create_collection(
        collection_name="startups",
        vectors_config=models.VectorParams(size=384, distance=models.Distance.COSINE),
    )
- Create a payload index for the
cityfield. You will filter search results by city later, and Qdrant needs a payload index (a lookup structure for one payload field) to filter on a field efficiently.
client.create_payload_index(
    collection_name="startups",
    field_name="city",
    field_schema=models.PayloadSchemaType.KEYWORD,
)
- Upload the data. Each
models.Documentholds the text to embed and the model name, and Qdrant Cloud turns it into a vector during the upload, which takes a few minutes.
EMBEDDING_MODEL = "sentence-transformers/all-minilm-l6-v2"

client.upload_collection(
    collection_name="startups",
    vectors=[
        models.Document(
            text=startup["alt"] + ". " + startup["description"],
            model=EMBEDDING_MODEL,
        )
        for startup in startups
    ],
    payload=startups,
    ids=range(len(startups)),  # Stable ids, so a rerun overwrites instead of duplicating
    batch_size=256,  # How many vectors will be uploaded in a single request?
    wait=True,  # Return only after all points are stored
)
Vectors are now uploaded to Qdrant.
Build the Search API
Now that all the preparations are complete, let’s start building a neural search class.
In order to process incoming requests, neural search will need the Qdrant client: it performs search queries, and Cloud Inference converts each query into a vector with the same model as the data.
- Create a file named
neural_searcher.pyand specify the following.
import os

from qdrant_client import QdrantClient, models

EMBEDDING_MODEL = "sentence-transformers/all-minilm-l6-v2"


class NeuralSearcher:
    def __init__(self, collection_name: str) -> None:
        self.collection_name = collection_name
        # Initialize Qdrant client, Cloud Inference embeds the query text
        self.qdrant_client = QdrantClient(
            url=os.environ["QDRANT_URL"],
            api_key=os.environ["QDRANT_API_KEY"],
            cloud_inference=True,
        )
- Write the search function. Add it to the
NeuralSearcherclass.
    def search(self, text: str) -> list[dict]:
        # Use the query text to search for the closest vectors in the collection
        search_result = self.qdrant_client.query_points(
            collection_name=self.collection_name,
            query=models.Document(text=text, model=EMBEDDING_MODEL),
            query_filter=None,  # If you don't want any filters for now
            limit=5,  # 5 the most closest results is enough
        ).points
        # `search_result` contains found vector ids with similarity scores along with the stored payload
        # In this function you are interested in metadata only
        payloads = [hit.payload for hit in search_result]
        return payloads
- Add search filters.
With Qdrant it is also feasible to add some conditions to the search.
For example, if you wanted to search for startups in a certain city, replace the search function with this version, which takes an optional city:
    def search(self, text: str, city: str | None = None) -> list[dict]:
        city_filter = None
        if city:
            # Define a filter for cities
            city_filter = models.Filter(
                must=[
                    models.FieldCondition(
                        key="city",  # Store city information in a field of the same name
                        match=models.MatchValue(value=city),  # Check if the payload field has the requested value
                    )
                ]
            )

        search_result = self.qdrant_client.query_points(
            collection_name=self.collection_name,
            query=models.Document(text=text, model=EMBEDDING_MODEL),
            query_filter=city_filter,
            limit=5,
        ).points
        payloads = [hit.payload for hit in search_result]
        return payloads
You have now created a class for neural search queries. Now wrap it up into a service.
Deploy the Search with FastAPI
To build the service you will use the FastAPI framework.
- Install FastAPI.
To install it, use the command
pip install fastapi uvicorn
- Implement the service.
Create a file named service.py and specify the following.
The service will have only one API endpoint and will look like this:
from fastapi import FastAPI

# The file where NeuralSearcher is stored
from neural_searcher import NeuralSearcher

app = FastAPI()

# Create a neural searcher instance
neural_searcher = NeuralSearcher(collection_name="startups")


@app.get("/api/search")
def search_startup(q: str, city: str | None = None) -> dict:
    return {"result": neural_searcher.search(text=q, city=city)}


if __name__ == "__main__":
    import uvicorn

    uvicorn.run(app, host="0.0.0.0", port=8000)
- Run the service in the terminal where you set
QDRANT_URLandQDRANT_API_KEY.
python service.py
- Open your browser at http://localhost:8000/docs.
You should be able to see a debug interface for your service.
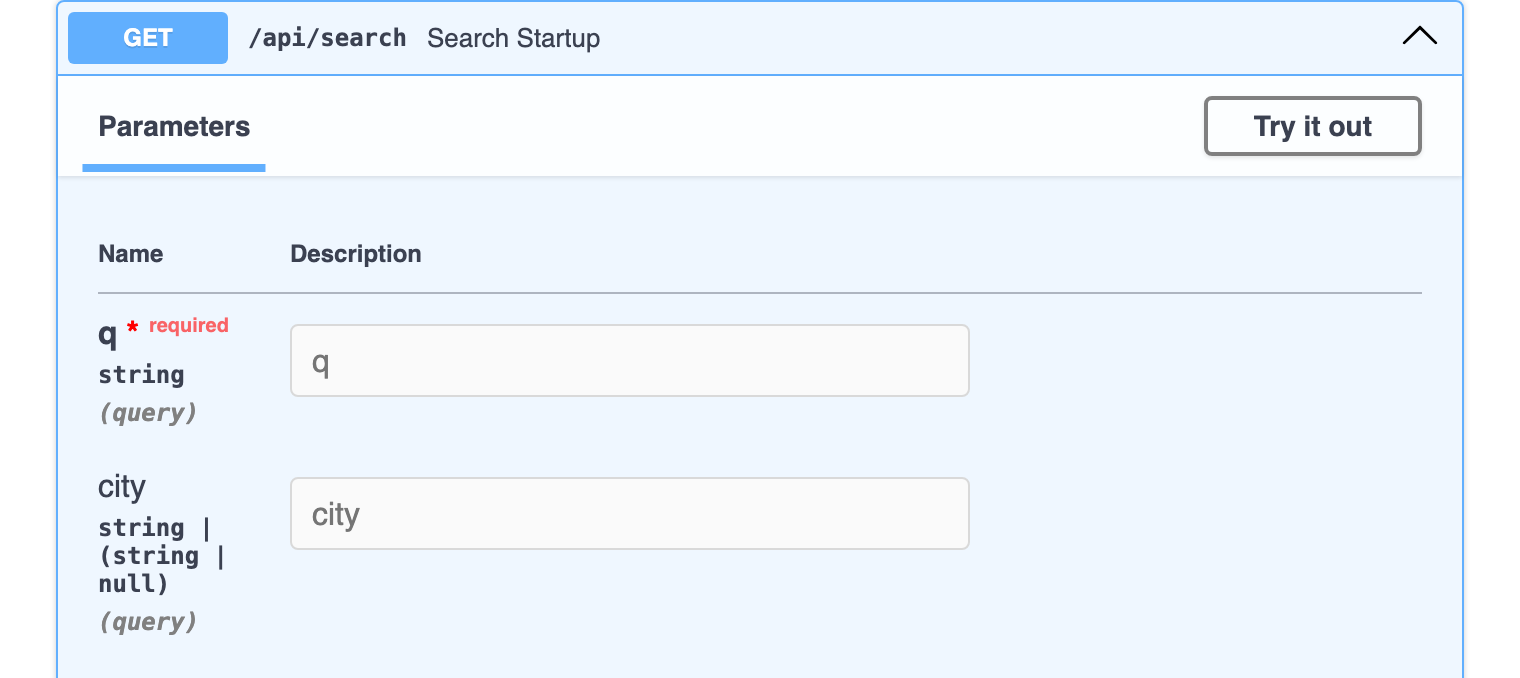
Feel free to play around with it, make queries regarding the companies in our corpus, and check out the results. For example, http://localhost:8000/api/search?q=cloud data platform&city=Berlin returns five Berlin startups, starting with:
{
  "result": [
    {
      "name": "Crate.IO",
      "images": "https://d1qb2nb5cznatu.cloudfront.net/startups/i/432840-0c2f2ca68e49eb8f716bd387a6f4bc86-thumb_jpg.jpg?buster=1404720084",
      "alt": "Crate.IO -  cloud computing storage big data big data analytics",
      "description": "The distributed Database for Docker\nAs big data proliferates, the need for a simple backend for data intensive applications – a data store – is obvious. It is also clear it will need to be 100% open source. This is Crate: an open source, super scalable and quick way to create a backend for the Internet ...",
      "link": "https://crate.io",
      "city": "Berlin"
    },
    ...
  ]
}
The other four are CloudWok, CrossCloud, Productsup, and infinipool.
Next Steps
A live online demo searches the same startup dataset. You can try it to get an intuition for cases when the neural search is useful. The demo contains a selector between semantic, keyword, and hybrid searches. You can switch between them to compare your result with a regular keyword search.
To combine both kinds of search in your own service, see Build a Hybrid Search API.
Join our Discord community, where we talk about vector search and similarity learning, publish other examples of neural networks and neural search applications.
 Ready to try Qdrant?